PaddleOCR Online · No install, open and go

PaddleOCR
Convert Any Document to Markdown in One Click

PaddleOCR reads everything from PDFs and scans to Word, Excel and PowerPoint and restores headings, paragraphs, tables, formulas and charts in their original reading order — outputting Markdown and JSON with coordinates, formulas recovered as LaTeX, molecular structures as SMILES, and tables kept intact across page breaks and merged cells. It supports 100+ languages, and the models run in the cloud, ready to call whenever you need them. With API access, a document ingestion pipeline takes just one minute to set up.

Pages parsed daily
1.2M+
Pages parsed daily
Supported formats
30+
File & web formats
Service uptime
99.9%
Service uptime

PaddleOCR Workbench

Upload · parse · export, all in one place

PDF / DOCX / PPTX / XLSX / HTML / PNG

files up to 10 MB · images up to 5 MB · PDFs up to 5 pages Upgrade to Pro

For PDF only. On: ignore the existing text layer and use OCR. Off: detect automatically. Other formats are unaffected.
Export formats Markdown · JSON · HTML · DOCX · LaTeX
Sign in to see your tasks

Your documents and results are saved to your account.

Sign in

Parsing in action

See what comes back from a real page

Handed the same document, a generic OCR gives you a wall of text. PaddleOCR keeps the structure, the chemistry, and the math.

Case 01 · Chemical structures

Figures and text → Markdown and JSON

Preserve figures, captions and reading order in downloadable Markdown and structured results.

Original PDF page
Scheme 2. J. Med. Chem. 2026, 49, 1128 Fig. 2. Structure of paracetamol HO NHCOCH3
PaddleOCR output
# figure and caption

{
  "type": "image",
  "img_path": "images/figure.jpg",
  "image_caption": ["Figure 2. Structure of compound 3a"],
  "page_idx": 6
}

# Markdown

![Figure 2](images/figure.jpg)
Generic OCRThe diagram is dropped as an image — all that survives is "see Fig. 2". No search, no computation.
PaddleOCRFigures and captions remain in the results for comparison with the original.
Case 02 · Math

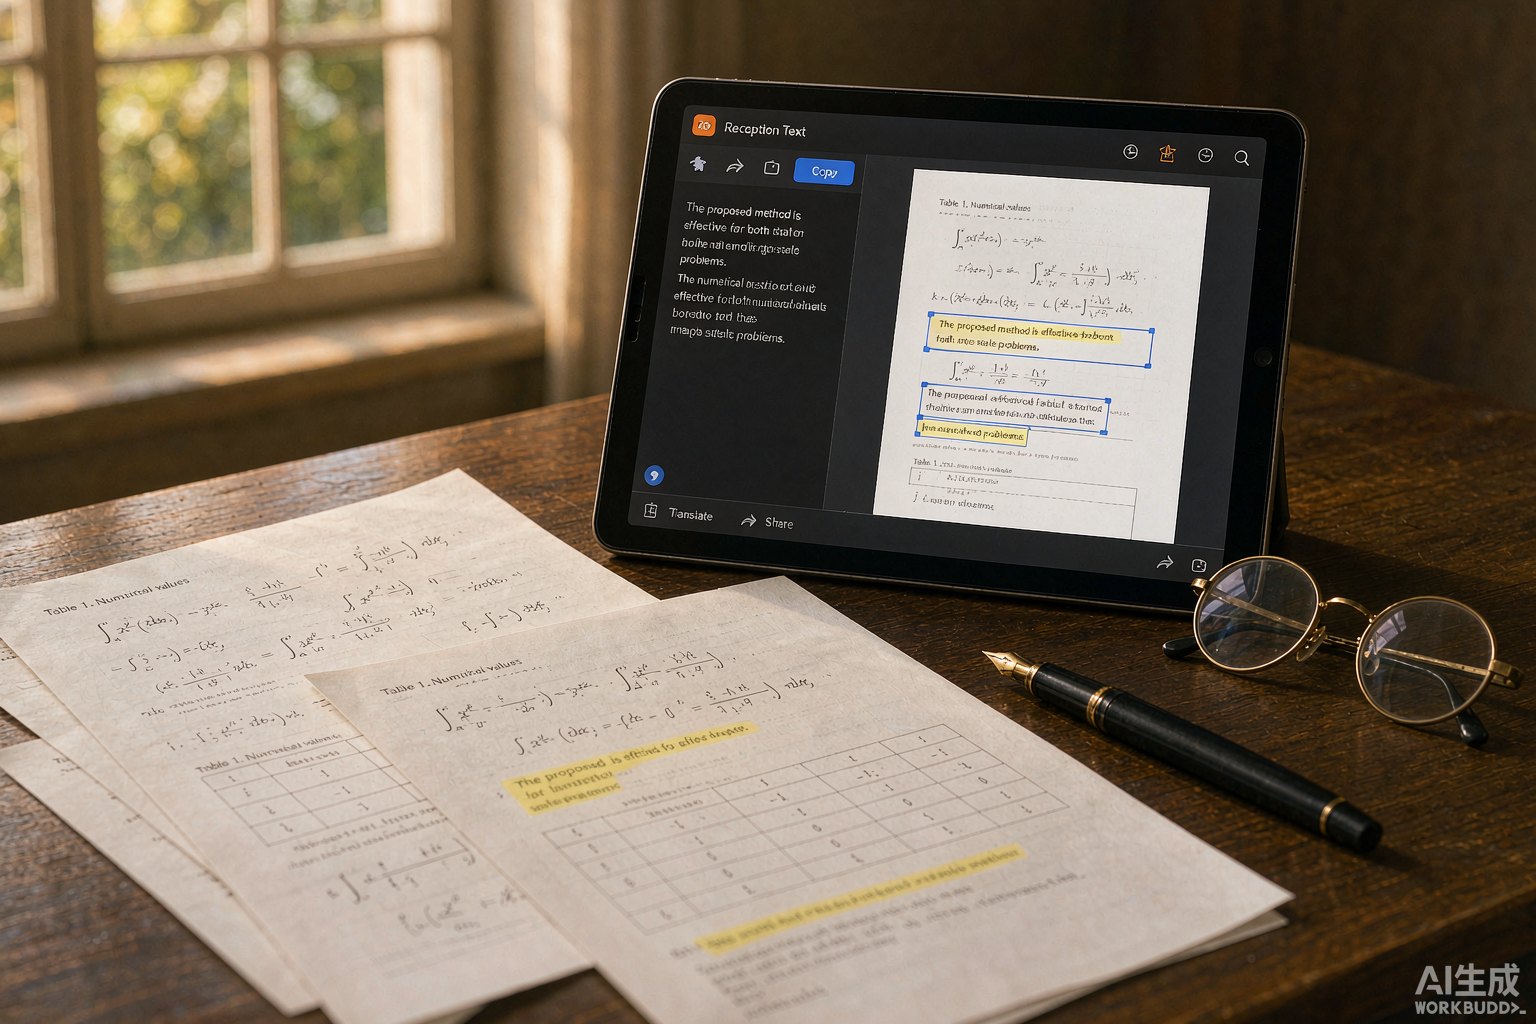
Formulas → clean LaTeX

Subscripts, radicals, fractions and Greek letters survive intact — output compiles as-is.

Original PDF page
PaddleOCR output
# standard LaTeX, renders as-is

\int_{0}^{\infty} e^{-x^{2}}\,dx

= \frac{\sqrt{\pi}}{2}


\frac{\pi^{2}}{6}

= \sum_{n=1}^{N} \frac{1}{n^{2}}


# human-readable text kept too

∫₀^∞ e^(−x²) dx = √π / 2
Case 03 · Complex tables

Merged headers & spanning tables → structured rows

Multi-level headers and tables that continue across pages are stitched back together, with cell coordinates intact.

Original PDF page
Table 3. Yield comparison, control vs. treatment GroupControlTreatmentMeanSDMeanSDSample A12.40.8318.91.02Sample B14.10.9121.31.14Sample C15.71.0524.61.28Sample D17.21.1126.81.35
PaddleOCR output
# merged headers flattened to Markdown

| Group | Control mean | Control SD | Treatment mean | Treatment SD |

| --- | ---:| ---:| ---:| ---:|

| Sample A | 12.4 | 0.83 | 18.9 | 1.02 |

| Sample B | 14.1 | 0.91 | 21.3 | 1.14 |

| Sample C | 15.7 | 1.05 | 24.6 | 1.28 |

| Sample D | 17.2 | 1.11 | 26.8 | 1.35 |


# coordinates & merges kept in JSON

{"rows": 5, "cols": 5, "merged": [2, 2]}

Capabilities

A parsing engine built for complex documents

Beyond text extraction. PaddleOCR understands the structure, semantics, and hierarchy of scientific layouts.

Chemistry · math · tables

01 / SCIENCE

Scientific layout understanding

Purpose-built for chemical formulas, mathematical notation, complex tables, and multi-column layouts — preserving reading order and logical structure.

Chemical formulasLaTeX mathSpanning tables
{"type":"title","level":1"bbox": [72, 96, 540],"text":"3. Methods"},"type":"table","html":"<table>…"}, …]Semantics · bbox · hierarchy

02 / AGENTS

Native to AI agents

Structured JSON with semantic tags for headings, paragraphs, tables, figures, and formulas — plug directly into RAG, knowledge bases, and agent workflows.

Structured JSONRAG-readySemantic tags
Layout0.42sFormulas0.61sTables0.77s100 pages · 1.8s total

03 / SPEED

High-speed elastic compute

Elastic cloud scheduling parses hundred-page documents in seconds, while batch jobs run in parallel to meet enterprise throughput.

Sub-second jobsParallel batchesElastic scaling

Who uses PaddleOCR

Built for research, engineering, and business teams

From one person's reading list to an organisation-wide knowledge base, PaddleOCR sits at the first gate where documents enter your systems.

A scientific researcher using PaddleOCR online to parse PDF papers and literature into structured text

Researchers

Scientific researchers

Turn papers, patents, and lab notes into searchable structured text in bulk. Formulas and chemical notation survive intact, so literature reviews stop being manual transcription.

A developer calling the PaddleOCR document parsing API and wiring the results into an application

Developers

AI application developers

One line of code. Get semantically tagged JSON straight into your RAG pipeline, knowledge base, or agent workflow — no parsing pipeline of your own to maintain.

A team reviewing document parsing analytics and dashboards on a large meeting room screen

Enterprise

Enterprise & institutional teams

Batch-ingest research reports, contracts, and archives. Pair it with on-premise deployment and usage reporting to make document assets genuinely searchable.

API reference

Integrate in one line, call it like a local function

A RESTful API and multi-language SDKs cover upload, status, and download — with clear error codes and webhooks so integration stays painless.

  • RESTful endpoints with cURL / Python / Node.js / Go examples
  • Choose synchronous responses or async jobs
  • Structured error codes with retry guidance
  • Webhook callbacks on completion, no polling needed
Read the full API docs
import os
import time
import requests

API = "https://YOUR_API_HOST/api/open/v1"
headers = {"Authorization": "Bearer " + os.environ["MINERU_API_KEY"]}
with open("paper.pdf", "rb") as source:
    response = requests.post(API + "/tasks", headers=headers,
        files={"file": ("paper.pdf", source, "application/pdf")},
        data={"is_ocr": "false"}, timeout=120)
response.raise_for_status()
body = response.json()
if body["code"] != 0:
    raise RuntimeError(body["msg"])
task_id = body["data"]["task_id"]
print("Task:", task_id)
deadline = time.monotonic() + 1800
while time.monotonic() < deadline:
    response = requests.get(API + "/tasks/" + task_id, headers=headers, timeout=30)
    response.raise_for_status()
    body = response.json()
    if body["code"] != 0:
        raise RuntimeError(body["msg"])
    data = body["data"]
    if data["task"]["status"] == "completed":
        with requests.get(data["results"]["full_zip_url"], stream=True, timeout=120) as result:
            result.raise_for_status()
            with open("result.zip", "wb") as output:
                for chunk in result.iter_content(1024 * 1024):
                    output.write(chunk)
        break
    if data["task"]["status"] in {"failed", "expired"}:
        raise RuntimeError(data["task"]["error"] or data["task"]["status"])
    time.sleep(3)
else:
    raise TimeoutError("Continue querying task " + task_id)

Pricing

Choose a plan that fits your needs. Upgrade anytime.

Online parsing and all five export formats. Choose the plan that fits your documents.

Free

Sign up and start right away

$0/ month

No payment method required

  • 5 free pages every day
  • PDF, Word, PPT, Excel, images, HTML
  • Files up to 10 MB · images up to 5 MB
  • PDFs up to 5 pages
  • Web access; API is not included
Start free

Pro · Monthly

Flexible access, one month at a time

$9.90/ month

USD · one-time payment

  • 1,000 pages every month
  • PDF, Word, PPT, Excel, images, HTML
  • Files up to 200 MB · images up to 50 MB
  • PDFs up to 200 pages
  • API access included
Go monthly

Pro also includes the daily free allowance. Monthly pages reset each month and do not accumulate. Outputs are retained for 7 days.

On-premise

Your data never leaves your premises

For finance, healthcare, government, and research institutions, PaddleOCR deploys fully on-premise: models and data run entirely inside your own network.

100%Data stays local
CompliantSecurity framework ready
24/7Dedicated support
Talk to us about deployment

Customer stories

  • A top-tier securities research institutePrivate parsing for an internal research knowledge base — 50,000 pages a day with zero data egress.
  • A tertiary hospital research departmentStructured extraction from medical literature and trial reports, fully compliant with research data rules.
  • A provincial government cloudDigitized archives of official documents powering intelligent search and Q&A.
An IT administrator and a researcher managing document data in an on-premise server room
Models and data stay inside your own network, meeting compliance requirements in finance, healthcare, and government.